Implementing the Local Resolver of Python in FAST-Python

Implementing the Local Resolver of Python in FAST-Python
Section titled “Implementing the Local Resolver of Python in FAST-Python”The goal of this blog post is to explain how I implemented a local resolver for FAST-Python. FAST-Python is on of the hardest project to implement this kind of algo, so reading this should help implementing any other local resolver for other languages.
What is local resolution?
Section titled “What is local resolution?”Local resolution is a symbol resolution pass: it links each named entity to the entity that declares it. In other words, for every occurrence of a name — read, write, call, import — it answers the question “where does this name come from?”.
In FAST-Python, after the model is imported from source, running the local resolver produces a model where every name usage points to its local declaration:
x = 1 # this is the declaration of `x`print(x) # this use of `x` is linked to the declaration aboveIt is called local because it only resolves declarations that live in the same file/model (in contrast to a global/system resolution that would also resolve calls to external libraries, standard modules, etc.). Once we went through the file, a name that is not declared anywhere in the file gets bound to a special FASTNonLocalDeclaration placeholder — it is a declaration for the model, but we know it refers to something outside.
Local resolution is the foundation on top of which our other analyses are built such as the Static Single Assignment (SSA). Without it, you cannot even tell whether two x in the code are the same variable. You can’t even say if a FASTPyIdentifier is a variable or not.
The API
Section titled “The API”The result of the resolution is exposed through two accessors available on every FAST entity (they live in the FAST-Core-Tools package of the base FAST project, so they are reusable across languages):
entity localDeclaration— from any use of a name, returns the entity that declares it (the first assignment, aFASTPyFunctionDefinition, a loop variable, an import…). If the name was not declared in the file, it returns aFASTNonLocalDeclaration.declaration localUses— from a declaration, returns all the entities that resolve to it (usages and other declarations that share it).
This is a bidirectional relationship: localUses is the exact inverse information of localDeclaration.
On top of those two, FAST-Python adds a set of convenience queries that only make sense once the resolution is done — and only for nodes that represent variables:
access allAccesses/allReadAccesses/allWriteAccesses— all the read/write accesses to the same variable.access internalAccesses— the attribute accesses and subscripts on the variable (x.y,x[3]).access allNodesUsingMe/access allStatementsUsingMe— the statements that use the variable.variable isResolvedVariable—trueif the node resolves to a local variable declaration (and is not a function, method, import or unresolved name).node usedVariables— all the entities in the subtree of the node that resolve to local variables.
The full list is documented in the analysis.md “Querying local resolver information” section.
Implementation: a Moose visitor
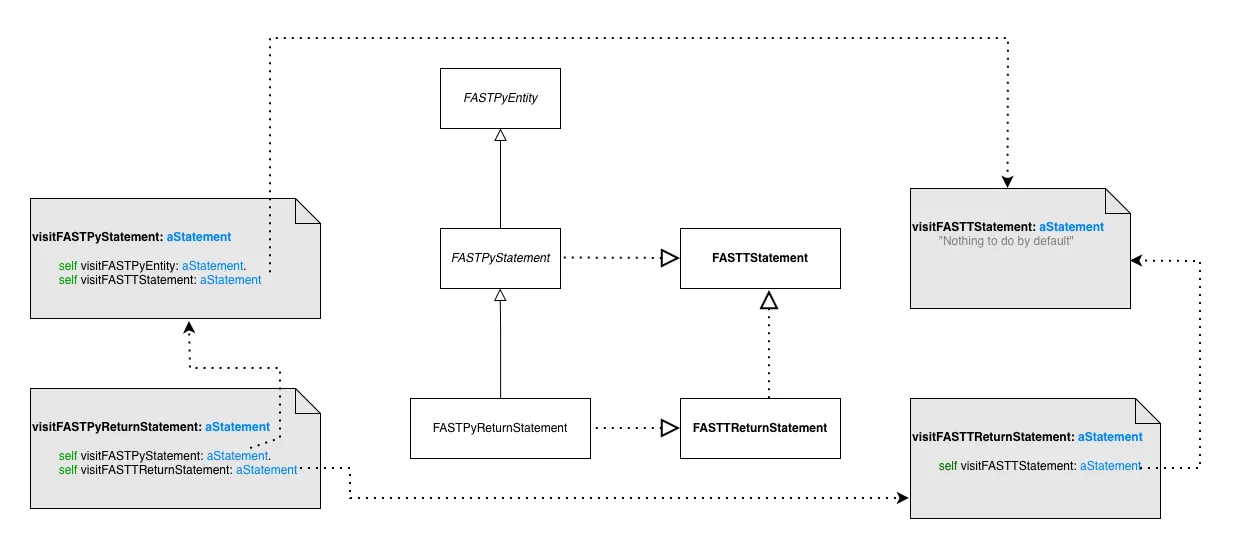
Section titled “Implementation: a Moose visitor”The resolver is implemented as a Moose/FAST visitor: FASTPythonLocalResolverVisitor. It visits a FAST model (a FASTPythonVisitor built on the generated visitor trait FASTPyTVisitor) and inspects/annotates the nodes in place.
If you are not familiar with how the visitor is generated from the model, I strongly recommend reading Improving the Visitor Generator first: it explains how FASTPyTVisitor is produced and how you can override the generated visitX: methods.
The Python problem: there is no declaration of variables
Section titled “The Python problem: there is no declaration of variables”Before we can write a single line of the algorithm, we have to deal with the first (and deepest) Python quirk: there is no declaration of variables.
In Java you get a real declaration:
int x = 1; // I declare and type `x`In Python, an assignment is the declaration:
x = 1 # this IS the declaration of `x`There is no keyword, no type, no way to distinguish “declare a fresh variable” from “reassign an existing one” syntactically — the same syntax x = ... does both. The resolver has to decide, and the decision is purely lexical reasoning about scopes and order, with no syntactic marker to lean on. Concretely:
- The first assignment in a scope is the declaration. The resolver must therefore know the order in which things appear, and which construct “creates” a scope.
- Parameters are declarations:
def f(x): ...declaresxas the function’s parameter. They are semantically the first assignment in the function’s scope. - Walrus operators (
x := ...) declarexinline, even inside an expression or anifcondition. - A
for ... in ...loop declares its target variable — but only the first time; it must be a declaration when the variable is not already known in the scope. - Augmented assignments (
x += 1) are uses + writes to the same variable. - For clauses in a list comprehension.
In our implementation this all boils down to a single rule expressed in visitFASTTCanBeVariable: (see below): a write access declares and bind, a read access binds. Everything else is scope management around that rule.
A scope stack
Section titled “A scope stack”The whole state of the algorithm is a single instance variable — and the class itself is tiny. Here is the complete class declaration:
FASTPythonVisitor << #FASTPythonLocalResolverVisitor slots: { #namesContext }; tag: 'CFG/LocalResolver/SSA'; package: 'FAST-Python-Tools'The superclass is FASTPythonVisitor (from the generated FASTPyTVisitor trait), so all the visitX: methods come for free: we only override the ones where the metamodel visit order differs from the resolution order.
namesContext is a stack of scopes (a Stack of Dictionarys, mapping name -> declaration). It is initialized in initialize:
initialize super initialize. namesContext := Stack newThe class entry point is trivial:
FASTPythonLocalResolverVisitor class >> resolve: aModule ^ self new resolve: aModuleand the instance resolve: wraps everything in one scope and runs the visitor:
resolve: aFASTBehaviouralEntity self useNewScopeDuring: [ "flush attributes in case this is not the first resolution" aFASTBehaviouralEntity withAllContainedEntities do: [ :entity | entity resetLocalResolution ]. aFASTBehaviouralEntity accept: self ] "<== Launch the resolution on the tree"Scopes are pushed/popped around the constructs that define a new scope (module, function, comprehension), through useNewScopeDuring::
useNewScopeDuring: aBlock namesContext push: Dictionary new. [ aBlock value ] ensure: [ namesContext pop ]The core operations
Section titled “The core operations”The algorithm is three small operations combined:
get— look a name up in the stack of scopes (from top to bottom):
declarationNamed: aName namesContext do: [ :scope | scope at: aName ifPresent: [ :declaration | ^ declaration ] ]. ^ nilset/ ensure a declaration — put a declaration in the current scope, handling re-declaration and shadowing (see Shadowing):
ensureDeclarationOf: aName declaration: aFASTNode in: scope scope at: aName ifPresent: [ :declaration | declaration localResolverKind = aFASTNode localResolverKind ifTrue: [ ^ declaration ] ifFalse: [ declaration shadowedBy: aFASTNode. aFASTNode ensureLocalUses. scope at: aName put: aFASTNode ] ] ifAbsentPut: [ aFASTNode ensureLocalUses; yourself ]bind— link a use to the existing declaration (creating aFASTNonLocalDeclarationif none is found):
bind: aFASTNode toDeclarationNamed: aName    ^ self bind: aFASTNode toDeclarationNamed: aName              ifAbsentUse: [ self ensureNonlocalDeclarationNamed: aName ]
bind: aFASTNode toDeclarationNamed: aName ifAbsentUse: aBlock    | declaration |    declaration := (self declarationNamed: aName) ifNil: [ aBlock cull: aFASTNode cull: aName ].    aFASTNode localDeclaration: declaration.    declaration addLocalUse: aFASTNode
What happens when no declaration is found
Section titled “What happens when no declaration is found”When a read has no matching declaration in any scope, bind:...ifAbsentUse: falls back to ensureNonlocalDeclarationNamed::
ensureNonlocalDeclarationNamed: aName ^ self ensureDeclarationOf: aName declaration: (FASTNonLocalDeclaration new name: aName; yourself) in: namesContext firstNote the scope: namesContext first is the bottom of the stack, so a FASTNonLocalDeclaration behaves as if it were declared at module level — reads of an undeclared name in a function and at module level end up in the same place. Also note that the fallback for attribute accesses and subscripts is slightly different (see the heart): declarationForUndeclaredNode:named: creates a local declaration on the first read of a subscript when the receiving variable has a declaration, and only resorts to the non-local declaration otherwise:
declarationForUndeclaredNode: aNode named: aName "In case of a subscript, if the receiving variable exists, we consider that the first read access to the subscript is the declaration." aNode isSubscript ifTrue: [ aNode value localDeclarationifPresent: [ :decl | ^ self ensureDeclarationOf: aName declaration: aNode in: namesContext top ] ifAbsent: [ "Nothing, just let the non local declaration." ] ]. ^ self ensureNonlocalDeclarationNamed: aNameThe heart: visitFASTTCanBeVariable:
Section titled “The heart: visitFASTTCanBeVariable:”Everything that can be a variable in FAST-Python implements the trait FASTTCanBeVariable (identifiers, attribute accesses, subscripts, walrus…). The visitor intercepts them in one place, and this is where “write declares / read binds” lives:
visitFASTTCanBeVariable: aTCanBeVariable    aTCanBeVariable isVariableWriteAccess        ifTrue:  [ self ensureDeclarationOf: aTCanBeVariable                            named: aTCanBeVariable localDeclarationName                            declaration: aTCanBeVariable ]        ifFalse: [ self bind: aTCanBeVariable                            toDeclarationNamed: aTCanBeVariable localDeclarationName                            ifAbsentUse: [ :node :name |                                self declarationForUndeclaredNode: node named: name ] ].
    super visitFASTTCanBeVariable: aTCanBeVariable
Two details make Python specific here:
localDeclarationNameis the name that will be used for scope lookup. It is not always the identifier text: an attribute access and a subscript use their source code as their name, sox.yandx[3]are treated as first-class “variables” (with known limits, see Limitations). Every named entity gets a default from the base FAST project (FASTTNamedEntity>>localDeclarationNamereturns#name); the Python classes only override it where the name is not the identifier:
"from FAST, the default for any named entity:"FASTTNamedEntity >> localDeclarationName [ ^ self name ]
"Python overrides:"FASTPyAttributeAccess >> localDeclarationName [ ^ self sourceCode ]FASTPySubscript >> localDeclarationName [ ^ self sourceCode ]isVariableWriteAccessdecides whether a node is a write access or a read access. It comes from FAST (FASTTEntity>>isVariableWriteAccess), but it delegates tovariableDeclarationwhich is anexplicitRequirement— every FAST project must implement it for the node kinds that can be variable write accesses. In FAST-Python, each relevant class provides its own logic to walk up the AST and check whether it sits in a write position:
"FAST core — the API:"FASTTEntity >> isVariableWriteAccess [    ^ self variableDeclaration isNotNil]
FASTTEntity >> variableDeclaration [    "If I am a node representing a write access, I return the node     assigning me. Else I return nil."    ^ self explicitRequirement]
"FAST-Python — an identifier checks whether it is the left side of an assignment, a for-loop target, etc.:"FASTPyIdentifier >> variableDeclaration [    | assignedNode |    assignedNode := self selfOrTopmostAssignableCollection.    assignedNode parentAssignmentLeft ifNotNil: [ :assignment | ^ assignment ].    assignedNode parentForStatementLeft ifNotNil: [ :for | ^ for ].    assignedNode parentForInClauseLeft ifNotNil: [ :clause | ^ clause ].    ^ super variableDeclaration]
"Parameters and walrus are their own declarator:"FASTPyParameter >> variableDeclaration [ ^ self ]FASTPyWalrus    >> variableDeclaration [ ^ self ]
"Attribute accesses and subscripts check for parentAssignmentLeft:"FASTPyAttributeAccess >> variableDeclaration [    self selfOrTopmostAssignableCollection parentAssignmentLeft        ifNotNil: [ :assignment | ^ assignment ].    ^ super variableDeclaration]
"The default on FASTPyEntity returns nil (not a write access):"FASTPyEntity >> variableDeclaration [ ^ nil ]
The interesting bit: for identifiers, variableDeclaration does not just check the immediate parent — it first walks through tuple/destructuring parents via selfOrTopmostAssignableCollection, so that in (a, b) = (1, 2) the individual a and b correctly return the tuple assignment as their declaration.
Reordering the visit, or dealing with Python scoping
Section titled “Reordering the visit, or dealing with Python scoping”Because the visitor is generated (see the visitor generator blog post), it visits the children of a node in the metamodel order. For a resolver, metamodel order is not always resolution order: a construct may declare a name in a part of the syntax that the generated visitor reaches too late (or too early) relative to its uses.
Our main tool is therefore: override the generated visitX: with a manual ordering of a few visitEntity:/visitCollection: calls — and be very careful about when to open a scope, because Python does not create a scope where you would expect one.
Block scoping is inconsistent: if and while
Section titled “Block scoping is inconsistent: if and while”In most block-structured languages you expect:
if (cond) { let y = 3; }use(y); // Compile error: y does not existPython does not create a scope for blocks. An if, a while, a for body do not introduce a new scope:
if cond: y = 3print(y) # 3, perfectly valid PythonCombine that with “assignment is the declaration” and you get leaks: a variable assigned inside an if branch or a loop is visible after the block. For the resolver this means no useNewScopeDuring: around branches — a name assigned in the then must be visible in the else and after the whole statement. What we do control is the order, which is important for shadowing: in an if, the semantics are
- the condition (can use outer variables, and
walrusoperators can even declare variables!), - the then clause,
- the elif clauses (in order),
- the else clause.
visitFASTPyIfStatement: anIfStatement "visit then - elif(s) -> else" self visitFASTTConditionalStatement: anIfStatement. self visitFASTPyStatement: anIfStatement. self visitEntity: anIfStatement thenClause. self visitCollection: anIfStatement elifClauses. self visitFASTPyTWithElseClause: anIfStatementNote that we do not call super here: the point is precisely to produce our own child order instead of the metamodel one.
while statements are similar, but the else clause has to go last (it runs when the loop condition becomes false):
visitFASTPyWhileStatement: aWhileStatement self visitFASTTConditionalStatement: aWhileStatement. self visitFASTTStatementBlock: aWhileStatement. self visitFASTPyStatement: aWhileStatement. self visitFASTPyTWithElseClause: aWhileStatementfor loops leak their variable
Section titled “for loops leak their variable”for i in range(10): passprint(i) # 9 — the loop variable is still there!The for ... in ... statement declares its loop variable in the enclosing scope (there is no loop scope). i survives after the loop. So a for is simultaneously a scoping and a declaring construct: the resolver must declare the target (left) in the current scope — no push — and, since that is the declaration, visit it before the iterable and the body:
visitFASTPyForStatement: aForStatement self visitEntity: aForStatement left. self visitEntity: aForStatement right. self visitFASTPyTWithElseClause: aForStatement. self visitFASTTStatementBlock: aForStatement. self visitFASTPyStatement: aForStatementFunction and method definitions: parameters are declarations
Section titled “Function and method definitions: parameters are declarations”The generated visitor does not visit the parameters before the body — but the parameters are declarations that the body uses. So visitFASTPyFunctionDefinition: manually visits parameters first, wrapped in a new scope, and does not use super:
visitFASTPyFunctionDefinition: aFunctionDefinition self ensureDeclarationOf: aFunctionDefinition named: aFunctionDefinition name declaration: aFunctionDefinition. self useNewScopeDuring: [ "do not use super: parameters must be visited before the body" self visitFASTTWithParameters: aFunctionDefinition. self visitFASTPyTWithTypeParameters: aFunctionDefinition. self visitFASTPyStatement: aFunctionDefinition. self visitEntity: aFunctionDefinition returnType. self visitFASTPyTDefinition: aFunctionDefinition ]visitFASTPyMethodDefinition: simply delegates to the function one.
Comprehensions: a scope that leaks itself, but not its body
Section titled “Comprehensions: a scope that leaks itself, but not its body”Comprehensions are Python 3’s attempt at “introduce an expression-level scope”, and they only partially succeed:
[x for x in coll]print(x) # NameError in Python 3 — x does not leak OUT of the comprehensionIn Python 3, the comprehension has its own scope, so the loop variable of its for clause does not escape. But the for clause(s) and the if condition(s) can still see and use variables from the enclosing scope, and the comprehension’s own variable is in scope through the whole comprehension (the body and the conditions can refer to the for clause variables).
That gives you a scope that is neither fully lexical like a function, nor absent like a block. In our implementation, visitFASTPyComprehension: opens a dedicated scope and reorders the visit so that the for clauses are processed before the conditions and the body (otherwise the conditions/body would be visited against the wrong scope):
visitFASTPyComprehension: aComprehension self useNewScopeDuring: [ self visitFASTPyTSplatExpression: aComprehension. self visitFASTPyExpression: aComprehension. self visitCollection: aComprehension forClauses. self visitCollection: aComprehension conditions. self visitEntity: aComprehension body ]We also had to choose a Python version:
Other constructs that declare names
Section titled “Other constructs that declare names”- Imports declare the imported name (or its alias) in the current scope —
visitFASTPyImport:ensures a declaration for each imported entity (usingaliasif present, source code otherwise). - Walrus operator
(x := ...)declaresx—visitFASTPyWalrus:ensures its declaration (it can even appear in anifcondition).
global and nonlocal statements
Section titled “global and nonlocal statements”Python is one of the rare languages where a function can explicitly opt out of local scoping:
x = 1
def f():    global x      # `x` is the module-level x, not a local one    x = 2
def g():    y = 1    def h():        nonlocal y    # `y` is the `y` of `g`, not a new local        y = 2
These two statements redirect resolution away from the current scope:
- a
global xmeans: “in this scope,xis the module-scopex”. Writes here target the global declaration, they must not create a new local declaration. - a
nonlocal xmeans: “xis the variable of the nearest enclosing function that defines it”. It is similar toglobalbut with a different target scope.
In the model, a FASTPyGlobalStatement (resp. FASTPyNonlocalStatement) contains a collection of variables, and each FASTPyVariable keeps the inverse parentGlobalStatement / parentNonlocalStatement pointer. That is what the visitor checks in FASTPythonLocalResolverVisitor>>#visitFASTPyVariable: — when visiting a variable that is the target of one of these statements, we change which scope the write will land in:
visitFASTPyVariable: aVariable    "We handle two specific cases here.     - global: the variables impacted should act as if they were in the       global scope. I ensure the variable is in the bottom scope and add       a copy in the current scope (so that if we assign it, it goes in       the global and does not create a new local).     - nonlocal: the variables impacted should act as if they were in the       first parent scope defining the variable."    aVariable parentGlobalStatement ifNotNil: [        namesContext top            at: aVariable localDeclarationName            ifAbsentPut: [ self ensureDeclarationOf: aVariable localDeclarationName declaration: aVariable in: namesContext last ] ].
    aVariable parentNonlocalStatement ifNotNil: [        namesContext allButFirst            detect: [ :scope | scope includesKey: aVariable localDeclarationName ]            ifFound: [ :scope | namesContext top at: aVariable localDeclarationName put: (scope at: aVariable localDeclarationName) ]            ifNone: [ self error: 'Non local statement points a variable that was never defined.' ] ].
    super visitFASTPyVariable: aVariable
Let’s unpack the two branches:
global— we want a writex = 2inside the function to target the module-levelx. So we look at the bottom scope (namesContext last, the module scope) and, ifxis not there yet, we declare it there with the current writing variable as its declaration. Then we copy a reference into the top scope (namesContext top). From then on, any write in this scope simply findsxpresent in the top scope —ensureDeclarationOf:sees the same kind (#variable=#variable) and keeps the same declaration, so no new local is created and the write silently targets the global one. The copy trick makes the subsequent writes “resolve” without us having to special-case every write site.nonlocal— the target scope is not the module but the nearest enclosing function that already defines the name. So we scannamesContext allButFirst(everything except the bottom scope) and re-bindxin the top scope to the existing declaration found there. If no enclosing scope defines the name, this is a Python error (SyntaxErrorat compile time in real Python), so we raise an error too.
Both branches rely on a nice property of our data structure: the top entry of the stack is always the current scope, and putting a reference to an existing declaration (rather than a fresh node) in the current scope is exactly what redirects future uses.
Shadowing in Python
Section titled “Shadowing in Python”Shadowing is another direct consequence of “no declarations”: in Python, anything named can shadow anything named, in the same scope:
x = 1 # Declaration 1: variablefrom os import x # Declaration 2: import (shadows Declaration 1)def x(): # Declaration 3: function (shadows Declaration 2) passprint(x) # links to Declaration 3The rule we implemented
Section titled “The rule we implemented”In ensureDeclarationOf: (see core operations), when a name is re-declared in the same scope, the resolver does not decide based on types (there are none) but on localResolverKind:
- if the new entity has the same kind (e.g. re-assigning a variable): we keep the same declaration and do nothing special. Two
x = ...in a row share one declaration. (This is whyensureLocalUsesinitializes the uses instead of resetting them: several nodes can be declarations of one shared declaration.) - if the kind is different (a variable shadowed by an import or a function): we create a new declaration, and link the two declarations together.
localResolverKind is not used anywhere else in the resolver — it exists only to drive this decision. Each node kind that can act as a declaration returns its kind, and the base FAST project provides no default because it is purely language-specific:
FASTPyIdentifier >> localResolverKind [ ^ #variable ]FASTPyParameter >> localResolverKind [ ^ #variable ] "can be reassigned"FASTPyWalrus >> localResolverKind [ ^ #variable ]FASTPyAttributeAccess >> localResolverKind [ ^ #variable ]FASTPySubscript >> localResolverKind [ ^ #subscript ]FASTPyFunctionDefinition >> localResolverKind [ ^ #function ]FASTPyMethodDefinition >> localResolverKind [ ^ #method ]FASTPyImport >> localResolverKind [ ^ #import ]Two subtleties we hit:
- Parameters are
#variable, not a dedicated kind, because they can be reassigned inside the body:def f(x): x = 2must share the declaration with the parameter, not shadow it. FASTPyEntity>>localResolverKindraises an error by default, which catches any node kind that is used as a declaration without having declared its kind — a cheap safety net while extending the metamodel.
The shadowing API
Section titled “The shadowing API”To make shadowing queryable, two back-links were added on the declarations (FASTPyEntity, in FAST-Python-Model, generated via the metamodel generator):
declaration shadowing— returns the declaration it shadows, ornil.declaration shadowedBy— returns the declaration that shadows it, ornil.
Together they form a linked list from the first declaration to the most recent one. Each declaration keeps its own localUses (the set of entities that resolve to it, not to its successors), and usages always resolve to the most recent declaration.
Going back to the example:
varDecl := model module statements first left.      "FASTPyVariable"importStmt := model module statements second.       "FASTPyImportFromStatement"funcDecl := model module statements third.          "FASTPyFunctionDefinition"
varDecl shadowedBy.        "=> FASTPyImportFromStatement"importStmt shadowedBy.     "=> FASTPyFunctionDefinition"importStmt shadowing.      "=> FASTPyVariable"funcDecl shadowing.        "=> FASTPyImportFromStatement"
varDecl localUses size.     "1  (just the assignment)"importStmt localUses size.  "1  (just the import)"funcDecl localUses size.    "2  (the definition + print(x))"
A caution about “same kind”
Section titled “A caution about “same kind””Same-kind re-declaration shares the declaration, which also means shadowing’s chain and local uses are independent of the SSA versioning: if you need to know which assignment impacts a particular use, local resolution is not enough — combine it with the SSA pass (it produces one version per assignment). The two analyses are designed to be composed in this pipeline order: Local resolution → CFG → SSA.
Known limits and what is left to do
Section titled “Known limits and what is left to do”We implemented local resolution for Python, but we focused on variables first, because that is what the CFG/SSA and the reachability analyses needed. Functions, methods and imports are handled in the scope bookkeeping (localResolverKind, reordering in the visitor), but if your mission is a complete Python symbol table, expect more work there (call graph resolution, self/class attributes, closures and bound variables…).
Specific known weaknesses (documented in analysis.md → Limitations):
- Attribute access chains:
x.y.z = 3; a = x.y; print(a.z)—a.zshould resolve tox.y.z, but it does not (only the source code of the attribute access is used as the name). - Subscripts are compared by source code:
y[x]with differentxvalues are conflated;x[0:4]andx[:4](semantically equal) are seen as different. Matching the expression instead of the string would fix it. - Instance variables (
self.x) cannot be handled correctly without knowing the order in which methods are invoked. - Python 2 scoping is not supported (comprehension variables leak in Python 2; we implement Python 3).
global/nonlocalare handled, butnonlocalerrors out if the variable was never defined in an enclosing scope.
Also, one of the future step zould be to make some parts, such as the context stack, generic and push it to FAST so that it can be reused in other FAST projects.
Quick start
Section titled “Quick start”"Import"model := FASTPythonImporter parseFile: aFile.
"Resolve"FASTPythonLocalResolverVisitor resolve: model module.
"Query"(model allFunctionDefinitions first) localDeclaration. "a FASTPyFunctionDefinition"The recommended pipeline for analysis:
model := FASTPythonImporter parseFile: aFile.FASTPythonLocalResolverVisitor resolve: model module.model allFunctionDefinitions first cfg. "CFG"FASTPythonSSAVisitor resolve: model allFunctionDefinitions first. "SSA (after resolution)"The local resolver and SSA require Python 3 scoping.
Advice for implementing it in your own FAST project
Section titled “Advice for implementing it in your own FAST project”- Use the generated visitor, override
visitX:selectively. You rarely need to reorder everything — only where the metamodel order differs from the declaration-before-use order (if,for,while, functions, comprehensions). - Model a scope stack explicitly. One
StackofDictionarys was enough for the whole algorithm. Wrap “new scope” sites in auseNewScopeDuring:/[ensure: pop] pair so the stack is popped even on error. - Make “what declares a name” explicit and language-aware. For Python: write access declares; read access binds;
fortarget declares in the enclosing scope; comprehensions open a scope;global/nonlocalredirect. - Add a
localDeclarationNameper node kind (it issourceCodefor attribute accesses/subscripts, the identifier name otherwise) — do not hard-code “the name is the text” everywhere. - Add a
localResolverKindand use it to drive shadowing. It made the Java-free, type-free Python shadowing tractable and gave us a cheap way to keep-or-split declarations. - Reset your attributes before re-resolving. We flush
localDeclaration/localUseson all contained entities at the start ofresolve:so the resolver is idempotent on a model.
The FAST-Python sources you will want to look at: FASTPythonLocalResolverVisitor, the localResolverKind/localDeclarationName extensions in FAST-Python-Tools.